1:08
Explore
FluidVoice - We built an under 1B speech-to-text model that outperforms both open
FluidVoice · Nov 2026 · 0:52 · AI-annotated
- Length
- 0:52
- Scenes
- 5 · 10.4 s avg
- Product on screen
- 0:00
- Voiceover
- Yes
00:00:00 / 00:52:02
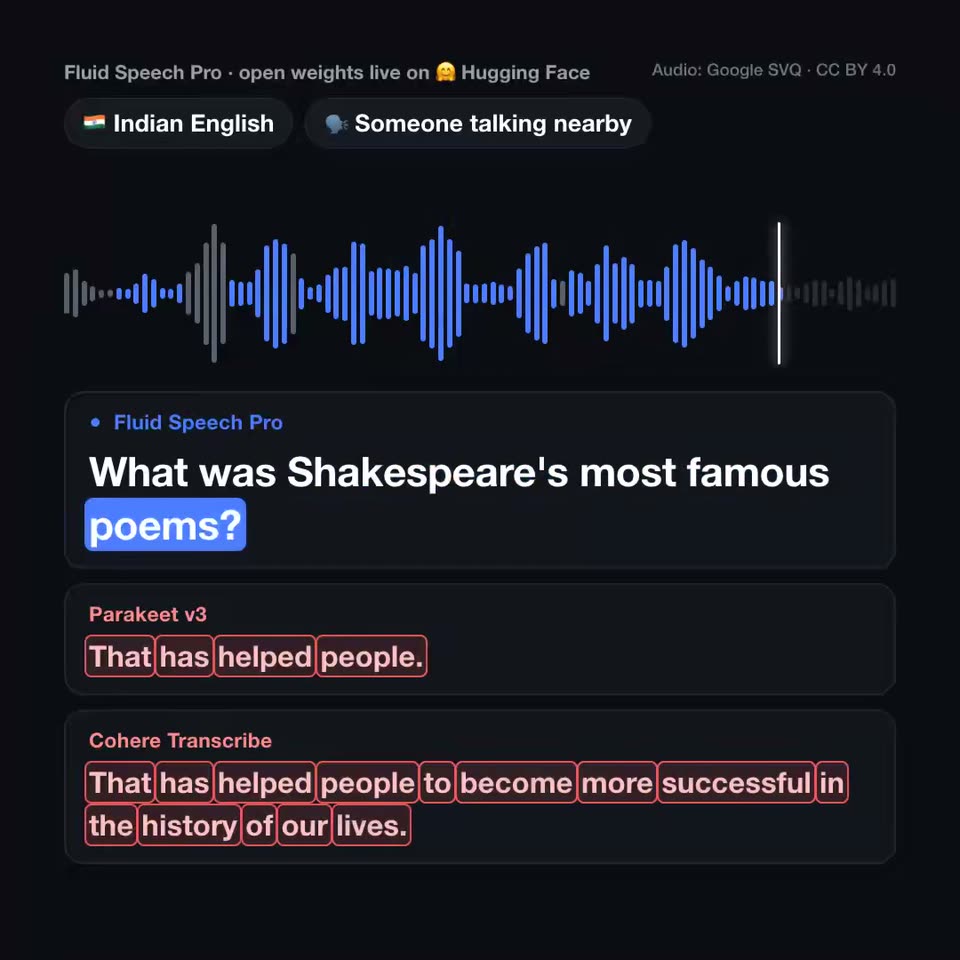
FluidVoice’s 0:52 launch film runs 5 scenes, about 10 s each. The product is on screen from the first frame. There is no explicit call to action; a voiceover carries the film. A single unbroken dark-UI shot where a waveform plays left to right while three stacked panels type the same sentence word by word, the hero model clean in white with a blue chip and the two rivals boxed in red errors. Rounds swap accents and background noise every few seconds, so the comparison reads as a steady, legible benchmark rather than a narrated pitch.
No filming indicatedEstimated needs: 2 capture groups — your screens or recordings
Is this your launch? to your site or press kit.
More like this
0:18
Shopify - the Shopify AI Toolkit is here manage your store with your favorite
Shopify · Business software · Apr 2026
0:15
FluidVoice - We built an under 1B speech-to-text model that outperforms both open, scene by scene
· 5 scenes as text
01 · Product intro · 0:00–0:18
Dark transcription-comparison UI on black. A blue waveform fills left to right as a playhead advances, while three stacked panels type the same sentence word by word. Correct words show white with a blue highlight box; errors show red boxes. Accent and noise tags change between rounds.
Techniques: Kinetic type
Camera: Static
02 · Demo · 0:18–0:24
A dark UI compares three speech transcriptions. A waveform plays left to right, its bars turning blue at the moving playhead. Three stacked panels type out word by word: the top in white with a blue highlight on the current word, the lower two in red-outlined word boxes.
On-screen text: “Fluid Speech Pro · open weights live on 🤗 Hugging Face”, “Audio: Google SVQ · CC BY 4.0”
Techniques: Kinetic type
Camera: Static
03 · Demo · 0:24–0:35
A dark UI compares three transcription models. A waveform playhead sweeps across, tinting played audio blue. Three stacked panels type captions word by word; the top row highlights the current word in a blue chip, the lower two box errors in red. A top pill swaps to “Someone talking nearby”.
Techniques: Kinetic type
Camera: Static
04 · Demo · 0:35–0:46
A dark UI compares three transcription models under a live waveform. As the playhead sweeps right, bars turn blue and three rows type out word by word, the active word boxed in blue or red. At 5.5 s the tag switches to 'Someone talking nearby' and the rows restart.
Techniques: Kinetic type
Camera: Static
05 · Demo · 0:46–0:52
A dark UI shows an audio waveform with a white playhead sweeping left to right. Below, three stacked panels type out transcriptions word by word, the top in white with a blue highlight, the two lower ones with red-outlined words marking errors.
Techniques: Kinetic type
Camera: Static